Singular Value Decomposition
When working with digital computers, no computation can be any more precise than the floating point granularity of the machine. When 4-byte IEEE floating point math is used, the smallest possible fractional error in any computation will be about 1E-7. For 8-byte IEEE math, the smallest possible fractional error will be about 1E-15. For the full 10-byte IEEE math used in 80x87s, the smallest attainable fractional error is in the vicinity of 1E-19.
Given that TableCurve 2D uses the full hardware precision 10-byte floating point for its standard linear fitting, you might think that finite floating point precision issues would not arise. This is certainly true for the linear equations with relatively few terms. It is not true, however, for higher order polynomial and rational equations.
Again, let us consider the following TableCurve 2D polynomial:
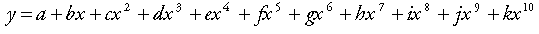
The design matrix for this equation will have a certain condition number. This number approaches infinity as the matrix becomes nearly singular. For the 64 bit mantissa of 10-byte IEEE floating point, a condition number greater than 264 (1.8E19) means significant roundoff and truncation losses will occur in conventional matrix processing.
As a matrix becomes more ill-conditioned or closer to singular, its condition number increases toward infinity and the determinant decreases toward zero. Such ill-conditioning plays havoc with conventional matrix procedures such as Gaussian Elimination, Gauss-Jordan, and LU-Decomposition.
As a rule of thumb, the maximum order polynomial that can be fitted conventionally is about tenth order for long double 10-byte math, and about eighth order for double precision 8-byte math. In general, all accuracy with a conventional algorithm can be considered lost when the condition number matches the floating point granularity (1E+19). This does not mean that a fit will look poor, however.
If data were generated for a tenth order polynomial to a full 19-digit precision using a set of properly scaled coefficients, it is reasonable to expect that the fitting algorithm should recover these values to some level of precision. At some stage in increasing order, however, all accuracy is lost in the recovery of these coefficients via a conventional algorithm.
SVD
Singular Value Decomposition, SVD, is a matrix procedure designed to handle ill-conditioning. The SVD procedure produces a vector of singular values. When the range of these singular values exceeds some optimum range based upon the floating point precision of the machine, the smallest singular values are set to zero.
This actually translates to the discarding of matrix information. The hope is that the information is so corrupted with error, that its omission is less harmful than its inclusion. In the case of the kinds of matrices generated by TableCurve 2D, this is not certain. In some instances, SVD will produce a far more stable set of coefficients with very nearly the same goodness of fit. In other cases, this zeroing of information may result in useless coefficients and a drastically poorer goodness of fit.
As a matrix becomes singular, the accumulated roundoff and truncation error in conventional matrix procedures tends to produce delicately balanced offsetting coefficients that push toward positive and negative infinity. Such coefficients are said to be unstable because a very small change in even a single input data point might result in a very different set of coefficients. Such fits are considered unstable because they can rarely be extrapolated in any way.
When a nearly singular design matrix is successfully processed by SVD, the fitted coefficients will be more stable. They will actually be forced toward zero rather than infinity by the floating point limitations SVD successfully manages. As a result, SVD fitted coefficients will look nothing like those fitted by conventional methods. They will be smaller in magnitude, and they will span a much smaller dynamic range. Small changes in input data will still result in similar coefficient values, and the fitted curve can often be extrapolated in a limited way with some success.
Limitations of SVD
If SVD is such a useful procedure, why does TableCurve 2D not use it by default for all linear fitting? One reason is computation time since the SVD procedure is about an order of magnitude slower than conventional matrix solution methods. Another reason is the unpredictable nature associated with this zeroing of singular values. Sometimes a significantly poorer least-squares fit results. Yet another reason is that for simpler equations where ill-conditioning is not an issue, the conventional methods produce a higher precision.